

Home / Case studies / AI Voice Tutor for Australian English Pronunciation in EdTech
Case study · EdTech & spoken language coaching · Conversational voice AI
AI Voice Tutor for Australian English Pronunciation in EdTech
An Australian EdTech startup needed learners to hear feedback on their Australian English pronunciation while they were still talking in a live conversation. Brainy Neurals built an AI voice tutor for Australian English that uses a realtime speech model to coach & score each spoken turn. The learner’s phone streams audio straight to the model, & a Python backend keeps each turn’s history in place of a human tutor’s notes. Learners now practice on first open with no account or schedule, & every utterance leaves three skill scores behind.
Published October 2026
At a glance
What problem did this solve?
Learners of Australian English had no way to get pronunciation feedback during a live conversation. Human tutoring was expensive to scale, & generic apps ignore Australian vowels.
What did Brainy Neurals build?
Brainy Neurals built a real-time AI voice tutor backend for an Australian EdTech startup. A hosted realtime speech model holds the conversation & scores every utterance as it lands.
What changed after it went live?
Spoken practice no longer waits for a human tutor’s diary. Feedback lands in the flow of conversation, & vocabulary, pronunciation & grammar scores build a record of progress.
Who else could use this?
Real-time voice coaching with per-utterance scoring fits any team that trains people to speak. Call centers, clinicians, sales teams & language schools all qualify.
| Fact | Detail |
|---|---|
| Industry | Education technology, spoken language coaching |
| Client type | Australian EdTech startup |
| Engagement | Voice tutoring backend |
| Timeline | Not disclosed |
| Capabilities | Generative AI, conversational AI |
| Delivery model | Project-based delivery |
Why did practice depend on human tutors?
An Australian EdTech startup needed an AI voice tutor for Australian English, because its learners could only get pronunciation feedback from human tutors. The product needed the ear of a private tutor & the patience of software. So the founder wanted a generative AI voice application that could hold the conversation itself & correct a learner’s actual sounds mid-flow, which is pronunciation coaching inside the talk rather than after it.
- Tutor hours. Every corrected sentence cost a slice of a tutor’s hour, so coaching stopped scaling with sign-ups.
- Wrong vowels. The apps the founder tried aim at American or British vowels, & Australian vowels sit elsewhere.
- Late feedback. Recording tools mark errors after the session, so a learner repeats one slip through a whole conversation.
- No record. Progress lived only in a tutor’s memory, with no per-utterance record of vocabulary, pronunciation or grammar.
- Sign-up first. Serious apps demanded an account before the first word, which is where casual learners leave.
None of that comes down to one learner’s ear. Phoneticians document the Australian English vowel system as its own target, separate from British & American varieties[1].
Why do the usual approaches stall?
The same four routes come up first, & each is sensible.
| Approach | What it gets right | Where it stops | Who it still suits |
|---|---|---|---|
| Private tutors | A real ear, real conversation | Hourly cost, one learner each | High-stakes exams, final polish |
| Big language apps | Habit, streaks, vocabulary drills | Built around American or British targets | Beginners building word stock |
| Record-then-grade tools | Detailed reports per recording | Feedback lands after the conversation | Solo review between sessions |
| Realtime speech model, our route | Correction inside the conversation | Weeks of turn-taking & scoring | Products where speaking is the point |
Timing is what makes the last row hard. A ten-language study found speakers minimize overlap & silence alike, with mean gaps within a quarter-second of the average[2].
Inside the AI voice tutor for Australian English
Brainy Neurals built the AI voice tutor for an Australian EdTech startup as one live audio stream between the learner’s phone & a hosted realtime speech model. One model carries the whole conversational AI role, & it hears & answers in sound with no transcript step between.
The first decision set where the backend sits, & we began by rejecting audio routed through our own servers. Every hop between a learner & the model adds delay & one more place to fail. So the app connects straight to the model, carrying a short-lived key minted per session. A leaked key buys nothing, because it expires with the session. The backend keeps to session keys, identity, history & configuration.
Our second decision split the tutor’s feedback into two separate channels. The tutor speaks its coaching aloud & files its scores silently, so the conversation never stops for a report card.
The tutor’s full instruction set lives in the database as data. A wording change reaches learners the same afternoon, with no deploy in the way.
Mitesh Patel set the streaming architecture & reviewed every change to the tutor’s spoken behavior, while Rushabh Shah built the voice loop, the scoring contract & the paired history writes described on this page.
The audio runs straight between the learner & the model, & the backend never touches it.
The technology stack we used
Eight layers went in, & each one had to earn its place near the audio. On a realtime voice build, choosing the stack through AI consulting is mostly a list of refusals, & those refusals kept the audio path at exactly one hop.
Voice loop
Speech model. A hosted realtime speech model that hears & speaks on one stream, instead of a three-model relay.
Turn taking. Server-side voice activity detection, which listens for the silence that ends a turn, so the model hears the pause instead of waiting on a push-to-talk button.
Backend & data
API service. Python, asynchronous throughout, so many idle sessions are held cheaply without a thread per session.
Data store. A document database, because turns & scores nest together in a way rigid conversation tables resist.
Identity. A one-way hashed device ID, a scrambled fingerprint of the phone that cannot be reversed, so nothing personal is ever stored & no email sign-up comes first.
Tutor config. Instructions stored as data, so wording changes without a deploy, rather than a prompt baked into code.
Clients
Mobile app. The client’s cross-platform app, one codebase for both platforms instead of two native codebases.
Test client. A terminal mic client that proves the loop without the app, in place of app-only testing.
What happens when a learner speaks?
One utterance, start to finish, in exactly the order the system hears it.
- The learner speaks. The app streams the raw audio to the speech model as the words are said, over one open connection.
- The pause ends the turn. Server-side voice activity detection hears the pause that ends the utterance & closes the learner’s turn for the model.
- Coaching streams straight back. The model streams its spoken coaching back, with a live transcript of both sides arriving as text.
- A silent score call. After the reply, the model silently calls a scoring function with vocabulary, pronunciation & grammar marks out of ten.
- One paired history record. The backend writes the learner’s words, the tutor’s reply & the three scores as one paired history record.
- The next utterance begins. The app plays the coaching aloud. The next utterance begins on the same open stream, with no redial anywhere.
Six steps end to end, & the backend never touches the audio.
What broke & how we fixed it
Three separate things went wrong, in this order, & every fix reads simple now.
The tutor read scores aloud
What broke. The tutor treated its scores as talk, reading marks aloud like a teacher handing back a test. On other turns it skipped the scoring call entirely. A warm persona & a silent bookkeeping duty pull against each other in one instruction set.
The fix. We tightened the score call into a strict contract, three whole numbers from zero to ten, & rewrote the instructions until filing scores became a reflex. The instructions also moved into the database, so wording changes ship without redeploys.
Turn detection clipped hesitant learners
What broke. Learners pause mid-sentence hunting a word, & the detector heard each pause as a finished turn. Turn-taking research agrees, because pause-length thresholds alone make a system interrupt people mid-speech[3].
The fix. We lengthened the silence the detector waits for before closing a turn, then tuned that wait against slow, hesitant learner speech. The barge-ins, where the tutor cut in over a learner, stopped.
Stored history came back scrambled
What broke. Transcripts, reply text, audio markers & score calls arrive as separate fragments. Naive writes produced orphaned turns & scores pinned to the wrong sentence.
The fix. We buffered each exchange’s fragments & wrote history once per completed turn, as a single paired record. Orphaned turns & mismatched scores disappeared with the same commit.
Flapping, the habit of softening a t between vowels, is why butter comes out closer to budda in quick Australian speech. American English does the same to its own t sounds.
Weeks like these are when a founder decides to hire AI developers rather than learn streaming audio the slow way. An AI proof of concept is where this failure class belongs, before launch dates get promised.
What changed once it went live?
The AI voice tutor for Australian English that Brainy Neurals built now runs in production behind the EdTech client’s mobile app. Each session opens with a freshly minted key & runs end to end on one audio stream to the realtime speech model. Paired history with three scores per utterance builds up quietly behind it.
We have not published latency, retention, accuracy or score-movement figures for this build. The client reports the loop feels immediate, but a number we have not measured is one we will not print.
| What | Before | Now |
|---|---|---|
| Who corrects the learner | A human tutor, by the hour | The tutor model, on demand |
| When feedback arrives | After the session, as notes | Inside the conversation, per utterance |
| What gets tracked | A tutor’s impressions | Three scores per utterance |
| Starting out | An account & a sign-up form | Speak on first open |
| Growing the learner base | More tutor hours | More concurrent sessions |
Day to day, a learner opens the AI voice tutor anywhere & starts talking. Every utterance leaves three data points behind it in history. The record survives across sessions because identity rides on a hashed device ID, with no login anywhere. Growth now costs concurrent sessions where it used to cost tutor hours.
Coaching wording is still tuned by the client without a deploy, because the tutor’s instructions live in the database, which is exactly what our AI engagement models aim for. The same paginated history feeds the app’s progress view, & a learner watches their scores move week by week.
The progress view is drawn, never screenshotted, & every score it shows already exists in prose.
Want a tutor like this in your app?
Tell us what your learners need to practice & how they talk today. We’ll say whether a realtime speech model fits your product, or you can check your AI readiness first.
What would we do differently now?
Four lessons came out of this build, two worth repeating & two worth avoiding.
Avoid tuning turn detection on fluent speech
We tuned turn detection on fluent speech & shipped the pain to actual learners. A tutor that interrupts a thinking pause teaches the learner to stop thinking. We now keep halting test recordings for every voice build, & we would not skip that again.
Repeat storing tutor instructions as configuration
The first wording changes each cost a redeploy. Moving them into the database made tuning ordinary editing, & the client kept that after handover. We would repeat this on day one.
Repeat keeping the backend off the audio path
This one held from day one & never needed revisiting. Everything the backend does can wait a beat, & the audio cannot.
Avoid building the test client halfway through
The terminal test client caught every audio failure, & we built it halfway through. Next time it exists before the first model call.
Where else does scored voice coaching fit?
Scored voice coaching runs a speech model inside a live conversation & rates each utterance, wherever speaking is the skill.
Clinicians rehearsing hard conversations
Teams using AI in healthcare rehearse difficult patient conversations against the same loop. The build swaps in a clinical rubric & stricter privacy handling.
Call agents drilling compliant wording
Call agents at firms using AI in banking & finance drill compliant wording with a tutor that hears every phrase. In the rubric, compliance wording replaces vowel targets.
Floor staff practicing product conversations
Retail floor staff practice product conversations before a shift starts. Product knowledge loads into the tutor’s instructions.
Crew drilling standard phrases under time
Aviation & hospitality crews drill standard phrases under time pressure. The build uses fixed phrase targets & noise-tolerant capture.
Managers rehearsing feedback & interviews
Corporate learning teams let managers rehearse feedback & interviews. Role-play personas swap out per scenario, & the loop stays put.
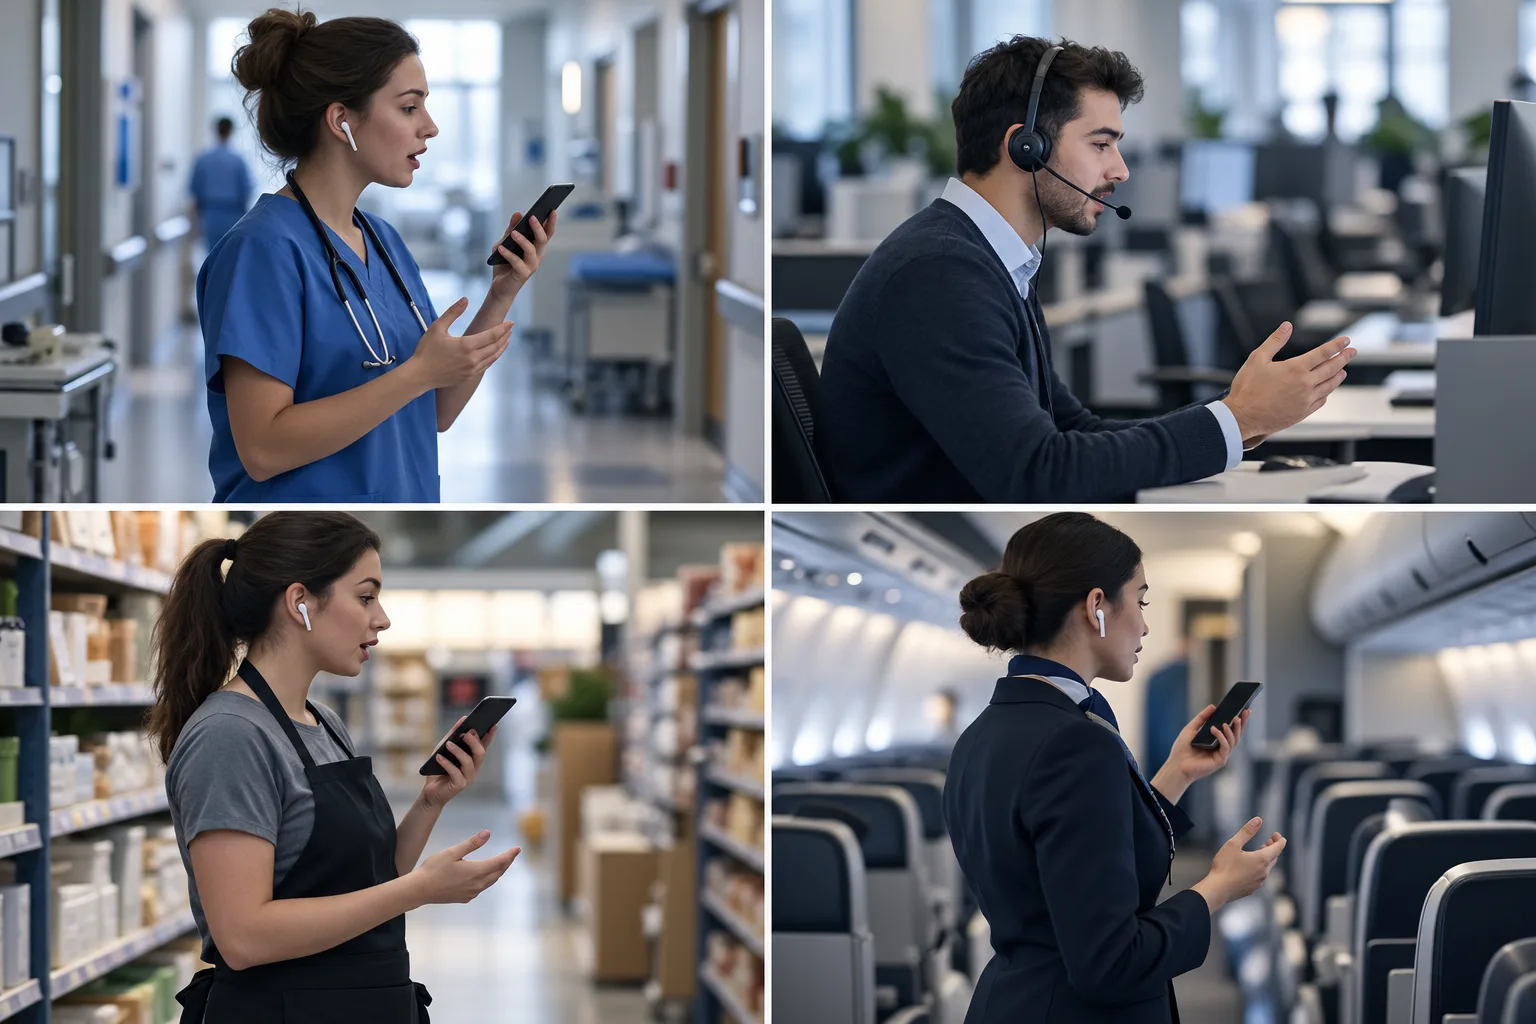
Porting this pattern needs a new rubric & rewritten tutor instructions. A test pass with the people who will actually talk to it comes last. The loop itself, one stream in & coaching plus scores out, carries over between domains unchanged.
Questions founders ask before building
Can AI give useful feedback on pronunciation?
Yes, within limits, & a realtime model hears the learner’s actual sounds. It catches a vowel drifting off target & says so before the next sentence starts. It won’t replace a phonetician & doesn’t need to.
How does an AI voice tutor for Australian English work?
A real-time AI voice tutor streams the learner’s audio to a speech model over one open connection. The model detects the end of a turn & speaks its reply back. Scores file through a silent function call while the conversation continues.
Why not chain speech-to-text, a chatbot & text-to-speech?
A speech-to-text, chatbot & text-to-speech relay works, & well-built versions are fast. What a transcript cannot carry is the accent. Once speech becomes text the vowels are gone, so a text model has nothing to coach. A speech-native model hears the sounds themselves.
How long does it take to build an AI voice agent?
A working voice loop on your own use case usually takes a few weeks. Turn detection, scoring behavior & history each need their own tuning pass with real users. A production backend follows once the conversation survives hesitant speakers.
How much does an AI voice tutor cost to build?
The cost depends on the conversation design & what already exists. Brainy Neurals scopes it from a short call & a look at your app, then quotes a fixed price, as it did for this EdTech client. An AI readiness assessment tells you whether a realtime model even fits.
What happens to a learner’s voice data?
The Australian English tutor streams audio for the session only. The stored history is text plus scores, tied to a hashed device identifier, never a name or email. What your product retains is a design choice made deliberately.
What should your app hear & coach?
Describe the speaking skill you want to coach, who your learners are & where they practice. We'll read it closely & come back with a plain answer on whether a realtime build fits.
Services behind this case study
Brainy Neurals ran this AI voice tutor build through six services, each linked below.
Generative AI applications
Voice AI products built on streaming speech models, from tutor instructions to production backends.
Conversational AI
Agents that hold a spoken conversation & call functions mid-turn, like this tutor’s silent scoring.
RAG development
Ground a tutor like this one in your own curriculum, so it teaches your material.
Edge AI & embedded services
For the day the tutor must work offline, speech models running on the device itself.
Hire AI developers
Realtime & voice engineers who extend your team when streaming audio gets difficult.
AI in healthcare
Patient-facing voice systems & clinical communication practice, built with privacy handled first.
An AI proof of concept is the fastest way to hear this on your own use case. AI consulting helps choose the model service first, & an AI readiness assessment tells you whether a realtime build fits. Our page on AI solutions by industry shows where conversational systems are already running for clients.
Similar case studies
One earlier Brainy Neurals build shares the shape of this AI voice tutor, with a model working under review gates.
AI Diet Assistant for Gastroenterology
Clinical dietary guidance generated under review gates, running live in a healthcare setting.
Cite this case study
Patel, Mitesh & Shah, Rushabh. AI Voice Tutor for Australian English Pronunciation in EdTech. Brainy Neurals, September 2026. https://brainyneurals.com/case-studies/ai-voice-tutor-australian-english/
Sources cited on this page
- Cox F, Palethorpe S. Australian English. Journal of the International Phonetic Association, 2007, 37(3), 341-350. DOI 10.1017/S0025100307003192.
- Stivers T, Enfield NJ, Brown P, Englert C, Hayashi M, Heinemann T, Hoymann G, Rossano F, de Ruiter JP, Yoon KE, Levinson SC. Universals and cultural variation in turn-taking in conversation. Proceedings of the National Academy of Sciences, 2009, 106(26), 10587-10592. DOI 10.1073/pnas.0903616106.
- Skantze G. Turn-taking in Conversational Systems and Human-Robot Interaction: A Review. Computer Speech and Language, 2021, 67, 101178. DOI 10.1016/j.csl.2020.101178.