

Home / Case studies / Generative AI Market Sentiment Analysis for Trading Firms
Case study · Financial services · Generative AI
Generative AI Market Sentiment Analysis for Trading Firms
An independent US trading analytics firm lacked market sentiment analysis, so one analyst read financial news by hand & often missed breaking stories. Brainy Neurals built a scoring pipeline that uses generative AI to find the company named in every news article & social post. The trading desk reads four news sources in parallel on one dashboard, beside live price data. Tickers resolve from the sentence with no manual lookups, & sentiment reaches the desk in seconds rather than minutes.
4
News sources read at once
Seconds
From news to the desk
From the sentence
How each ticker resolves
Published October 2026
At a glance
Brainy Neurals turned a US trading analytics firm’s manual news reading into a scored feed that sits beside live price.
What problem did this solve?
An independent US trading analytics firm tracked market news by hand, so coverage stopped where one analyst’s attention stopped. Stories that mattered were often read hours late, & some were never read.
What did Brainy Neurals build?
Brainy Neurals built a scoring pipeline for an independent US trading analytics firm. News articles, video transcripts, social posts & forum threads each get a score, which is then joined to live price data. Generative AI works out which company each story is about.
What changed after it went live?
Sentiment now reaches the desk as a scored signal instead of a reading list. Tickers resolve on their own & duplicate stories collapse into one event, so nothing is processed twice on a rerun.
Who else could use this?
Beyond AI for capital markets, any team that must react to public text at speed can use this pattern. Supply chain, insurance, commodity & brand risk desks face the same flood of posts.
| Engagement fact | Detail |
|---|---|
| Industry | Financial services, trading analytics |
| Client type | Independent US trading analytics firm |
| Engagement | Market intelligence platform |
| Timeline | Not disclosed |
| Capabilities | Generative AI & data engineering |
| Delivery model | Project-based delivery |
Why couldn’t the desk read fast enough?
An independent US trading analytics firm couldn’t read fast enough, because it had no market sentiment analysis while news volume climbed. News worth trading on came from four national publishers, finance video channels, social posts & forum threads.
No software read the news for the analyst, & no large language model was in place to help. That kind of AI reads text much as a person does, & wiring it into a desk is LLM development work. One analyst covered what they could, & the rest went unread.
- A headline landed at 6:40 in the morning & wasn’t read until 9:30.
- Somebody watched 40 minutes of video to find the 90 seconds that mentioned a holding.
- A company showed up under a name nobody had mapped to a ticker, so the story never reached the firm’s watchlist.
- One event came from four publishers, got counted four times & looked like a trend.
- A lunchtime spike in social chatter went unseen until morning.
A 2011 study timed London-listed stocks reacting to news in 20-second intervals[1]. In that study’s data, relevance filtering was the step that split useful signal from noise.
Why do the usual approaches stall?
Three of the four common ways to handle a flood of market news stall, even though each one makes sense on its own terms.
| Approach | What it gets right | Where it stops | Who it still suits |
|---|---|---|---|
| Read it yourself | Keeps judgement on every story | Stops at one reader | Small watchlists, slow sectors |
| Keyword alerts | Fires instantly & cheaply | Fires on words, ignores tone | Compliance flags, name monitoring |
| General sentiment tool | Scores any text at once | Reads finance as plain English | Reviews & support tickets |
| Domain scoring & price, our route | Reads tone & price together | Takes weeks of pipeline work | Desks reading text daily |
Reading by hand keeps judgement but stops at one reader, while keyword alerts fire fast & ignore tone. A general sentiment tool scores any text at once, but it reads finance as if it were plain English.
A 2011 study checked 50,115 company filings against a general-purpose word list[2]. Nearly three quarters of the words that list flags as negative aren’t negative in finance.
Three of the four routes stop at a wall, & only domain scoring joined to live price runs past all of them to the signal.
How we designed the scoring pipeline
We designed the scoring pipeline as a set of collectors feeding one scoring layer, with a database between them. Every source, from news sitemaps to video channels, gets a worker process of its own. Every score lands in one table, keyed to a ticker & a timestamp.
Without a price beside it, a sentiment score is an opinion with a number attached, so price joins every row.
Every collector writes into one store, & every score leaves it keyed to a ticker.
The first decision was where the sentiment score should come from. We ran two scorers, because a filed news article & a forum post are different kinds of text.
A financial sentiment model reads the articles & transcripts. A faster lexicon scorer takes the short posts by rating each word against a tone list.
The second decision was what turns a score into a trading signal. Instead of hand-written thresholds, we trained a model in house on the joined data. In that data, each score sits beside its price & its technical indicators, which are chart measures built from price & volume.
The model returns a direction & a confidence weight, & AI workflow automation decides what reaches the dashboard. The sentiment model was never the interesting part, because everything around it made the score worth reading.
Mitesh Patel reviewed every scoring decision against what the client could actually trade on. Brainy Neurals delivered all of it as a market intelligence platform, on a project-based engagement that combined generative AI with data engineering.
Which technology stack runs the pipeline?
The pipeline runs on a technology stack built to survive a market open & keep throughput steady when one source goes quiet. Transcription runs at the edge on the client’s own hardware, & entity reading calls a hosted language model in the cloud. Results then reach the desk over the web.
News from publisher sitemaps
Four workers read publisher sitemaps & keep only same-day stories at the source, which beat crawling front pages.
Video through local transcription
A channel watcher picks up new videos, & on-device inference on the client’s hardware turns the audio into text. Audio never leaves the building, which ruled out paid transcription.
Social posts from two collectors
Browser & API collectors run on one schedule, so two kinds of source behave as one with no aggregator in the middle.
Articles through a financial model
A financial-domain model scores articles & transcripts, because it reads finance as finance where a general lexicon can’t.
Social posts through a lexicon
Short posts go to a fast lexicon scorer, because speed beats nuance there.
Entities from a language model
A hosted language model names the company & ticker in each story, so there’s no ticker dictionary to maintain.
A signal model trained in house
The signal model was trained in house & quantized, meaning compressed to run on less memory, so it stays owned & small to serve. That ruled out calling an assistant on every item.
One store behind one API
A relational store sits behind a production API, so every reader works from one schema instead of a notebook prototype.
How does market sentiment analysis score one article?
The pipeline scores one news article in six stages, running from collection to a signal the desk can use.
One article travels through six stages, & the database is checked at both ends of the run.
- Read the sitemap. A collector reads the publisher’s sitemap, keeps whatever came out today & skips every link already in the store.
- Clean & cluster. The article text is pulled & cleaned. It’s then checked against scored stories so one event counts once.
- Score & tag. A financial-domain model scores the cleaned text, while a hosted model reads it for company names & tickers.
- Join the price. Price history & technical indicators for those tickers are pulled & lined up against the score by timestamp.
- Return a signal. The in-house signal model returns a direction & a confidence weight.
- Save & mark done. The signal lands in the store for the dashboard to pick up, & the article is marked so it never reruns.
Six steps run in order, & a person only steps in at the last one.
What broke & how we fixed it
Four things broke while Brainy Neurals built this pipeline, roughly in the order below, & each needed its own fix.
Duplicates tipped the average
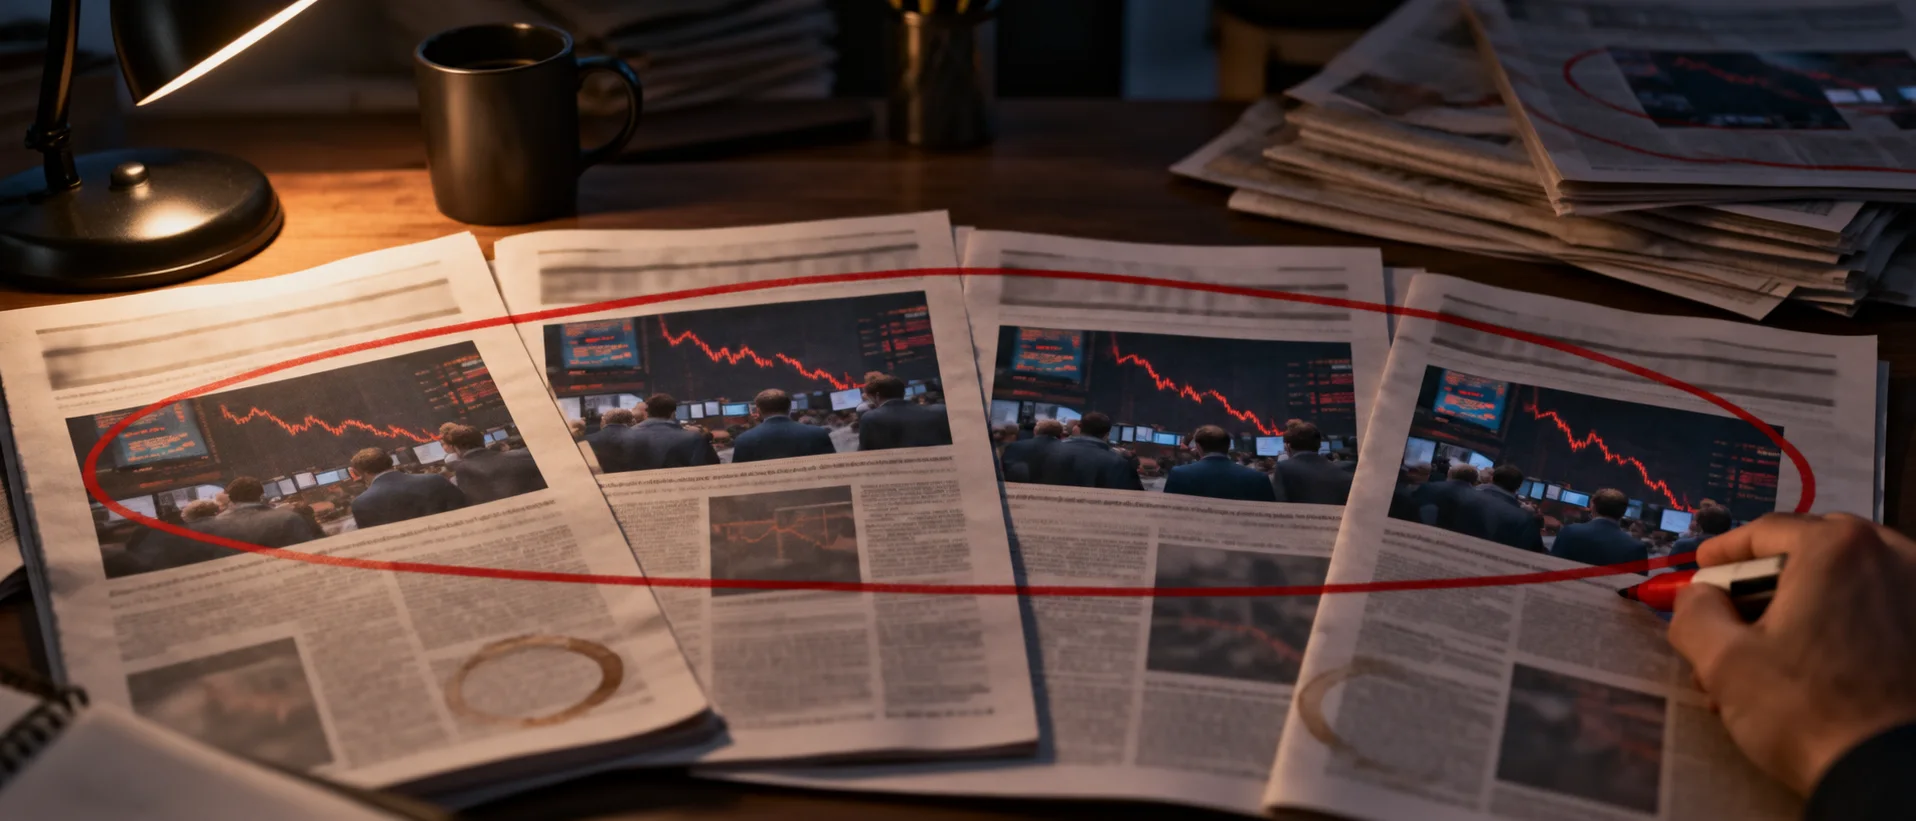
The first scoring run made a quiet Tuesday look like a crisis. Four publishers had covered one regulatory story, each collector scored its own copy & the average tipped negative.
The fix was to cluster stories before scoring, so one event becomes one record & the daily average counts events rather than column inches.
Company names resolved wrongly
A fruit company & a payments firm both resolved to the wrong instrument through a shared ticker. Research on similarly named securities found returns & volatility moving together for two unrelated firms[3].
Now a model reads the sentence around each name instead of a lookup table, & it holds back any name it can’t resolve.
Video ran past the close
Transcribing a day of channels on one machine took until evening, so the video queue ran longer than the trading day it covered. Every rerun started again from the beginning.
Now each processed video & its transcript go into the database, so reruns skip finished work & the run ends inside the day.
Collectors failed without a sound
The social collectors broke twice when a source changed its markup. Both times the run failed quietly, which hides the gap for longer than a loud failure would.
We wrapped every collector so a broken source marks itself down. The rest of the run carries on, & the dashboard shows what’s missing.
Four reports of one event collapse into a single record, so the event gets scored once instead of four times.
The collector failures landed in the weeks when a client starts asking about bringing in specialist engineers. Problems like these four are what an AI proof of concept exists to bring out early. The word ticker comes from the sound the old stock tape machines made.
What changed after go-live?
After go-live, the change shows up as six before-&-after facts, since the client shared no outcome figures & hasn’t disclosed the timeline.
News sources read in parallel
Four national publishers are now scored at the same time, where one analyst used to cover what they could.
No manual ticker lookups
Every ticker now resolves from the sentence around the name, so nobody looks one up by hand.
News & price on one dashboard
News & social posts now meet price data in one joined row.
We won’t print a number we didn’t measure, so we haven’t published accuracy or latency figures, or a return. The client does report that sentiment now reaches the desk in seconds rather than the minutes it used to take.
| Dimension | Before | Now |
|---|---|---|
| How the news gets read | Only one analyst, by hand | Four sources, in parallel |
| Video commentary | Watched end to end, sometimes | Transcribed & scored daily |
| Ticker identification | Looked up by hand, or missed | Resolved from the sentence |
| One story, four publishers | Counted four times | One clustered event |
| Sentiment & price | Split across two screens | One joined row |
| Work repeated on a rerun | All of it | None of it |
Coverage no longer depends on who’s at the desk that morning. A story that breaks before 7 am is already scored & priced, with its ticker attached, by the time anyone opens the dashboard. Adding another ticker costs nothing, because nothing was sized around one person’s reading speed.
For every story it reads, market sentiment analysis now leaves a direction, a confidence weight, a ticker & a timestamp in one table.
The pipeline is deployed & runs daily in production against the same four news sources it launched with. Video channels & forum threads feed the same scoring layer as social posts, & the dashboard reads from one store.
Since handover, the client has added tickers without touching a single collector. Everything is keyed to the ticker rather than the source, which made that possible. Nothing in the design assumes one corner of finance, which is why equities & macro coverage can share the same collectors.
The prototype the work started from hasn’t been reopened since handover.
Have sources your desk can’t keep up with?
Tell us which sources you’re losing, or check first whether your data can carry a signal. Either way, the person who would architect the build replies.
What would we do differently?
We’d keep the four fixes that held & drop the four habits that cost this build time. A score tied to the wrong instrument is worse than no score, so entity resolution leads the second list.
What we’d keep next time
- Cluster first, so every daily average counts events rather than column inches.
- Key everything on the ticker, so adding more tickers later never means touching a single collector.
- Store every item, so a rerun skips finished work & ends inside the day.
- Let every source report its own failures, so one broken source never stops the whole run or hides a gap.
What we’d avoid next time
- Budgeting days for entity resolution, which means matching each name to its company, when it took weeks.
- Scoring before clustering, which made every early average wrong in a plausible way.
- Running an overnight queue, which is useless to someone trading at 10 am, when ours finished at 4 pm.
- Staying on the prototype, which made the second month slow after a fast first demo.
Where else does sentiment scoring fit?
Sentiment scoring fits anywhere a team must react to public text, because it ties each tone score to the thing the text names. In market sentiment analysis, that score sits beside the price in the same row.
The same scoring pattern watches a supply route.
Supply chain risk desks
In supply chain work, the same problem is port strikes that surface in local press first. Suppliers replace tickers, so each score attaches to the supplier a story names.
Insurance catastrophe watch
For insurers, catastrophe chatter shows up before the wave of claims arrives. Geography becomes the join key, so a score attaches to a place instead of a stock.
Energy & commodity trading
In energy & commodities, news of an outage moves a physical price. The price feeds in that version come from exchanges rather than from stock data.
Retail product sentiment
In retail, product sentiment turns before the sales numbers do. Scoring runs on reviews & posts, & the product takes the place of the ticker.
AI trade surveillance & compliance
Compliance teams running trade surveillance need tone as well as words, because keywords alone miss it. Every score is kept for audit in that version of the build.
Porting the pipeline takes a new entity vocabulary & a different price feed, & the signal model needs retraining. A supply chain desk asks the same question a trading desk asks. Retail teams ask it about products instead of instruments.
What do buyers ask about sentiment pipelines?
Buyers ask these six questions about sentiment pipelines on almost every call, & Brainy Neurals answers each one below.
Can sentiment analysis predict market movements?
Sentiment analysis works as one input to a trading signal beside price & volume, & it can’t predict prices on its own. You get a measure of the tone of what gets published & how fast that tone shifts.
How is sentiment analysis different from technical analysis?
Technical analysis reads price & volume history on a chart, while sentiment analysis reads the language around an instrument & scores its tone. A system that joins the two lets you see a move forming & the reason being written at the same time.
Why use a financial sentiment model instead of a general one?
A financial sentiment model scores finance text the way a market participant would, which a general model can’t do. General models learn from ordinary English, where words like liability & cost read as negative. In financial reporting, you’ll find those words are completely routine.
How long does a market sentiment analysis build take?
A working proof of concept on two or three sources usually takes a few weeks. A production version with a dashboard follows once the daily run holds steady. Before launch, entity resolution & clustering each need a pass of their own, & so does throughput.
What does a sentiment pipeline like this cost?
Cost depends mostly on how many sources you need & how much of that is video, & training a signal model adds to it. We scope the work from a short conversation about your sources. An AI readiness assessment tells you first whether your data carries a signal.
Does a pipeline like this need a dedicated team?
A pipeline like this runs on a schedule & needs someone watching the collectors rather than a dedicated team. Retraining the signal model happens now & then as well. Publishers change their markup without warning, so source upkeep takes more time than the data science ever does.
Tell us what your desk reads each day
List the sources your desk reads & what it misses today. We'll tell you how a scoring pipeline would handle them.
Services behind this case study
The services behind this case study are the six Brainy Neurals practices that built the pipeline.
Generative AI applications
Language models go to work on real text, with collection & scoring built around them.
AI agent development
Scheduled pipelines keep running when a source breaks, & they decide what reaches a person on the desk.
Edge AI & embedded services
Transcription stays on your own hardware, so the audio never leaves the building.
RAG development services
Retrieval-augmented generation grounds a model’s answers in documents you’ve already scored, so a signal can show its sources.
Hire AI developers
Data engineers & language specialists join your team for the weeks when the sources fight back.
AI in banking & finance
Scoring & signal work suits firms whose raw material is text & price.
A quick pilot tells you whether your sources carry a signal at all, well before anyone commits to a full build. AI consulting helps decide which of your sources are worth collecting first, & in what order.
If you’re not sure where to start, a readiness check reads your data first. The industries hub shows where else this kind of work runs.
Similar case studies
Similar case studies show the same build discipline in other settings, starting with a clinical AI assistant.
AI Diet Assistant for Gastroenterology
Clinical dietary guidance is generated under review gates & runs live in a healthcare setting.
All Brainy Neurals case studies
Browse every published Brainy Neurals case study in one place.
Cite this case study
Shah, Rushabh. Generative AI Market Sentiment Analysis for Trading Firms. Brainy Neurals, September 2026. https://brainyneurals.com/case-studies/market-sentiment-trading-signals/
Sources cited on this page
- Groß-Klußmann A, Hautsch N. When machines read the news: Using automated text analytics to quantify high frequency news-implied market reactions. Journal of Empirical Finance. 2011, 18(2), 321-340. DOI 10.1016/j.jempfin.2010.11.009
- Loughran T, McDonald B. When Is a Liability Not a Liability? Textual Analysis, Dictionaries, and 10-Ks. The Journal of Finance. 2011, 66(1), 35-65. DOI 10.1111/j.1540-6261.2010.01625.x
- Rashes MS. Massively Confused Investors Making Conspicuously Ignorant Choices (MCI-MCIC). The Journal of Finance. 2001, 56(5), 1911-1927. DOI 10.1111/0022-1082.00394